When teams ask how to model data products, they usually start with the wrong question: should we use a star schema, Data Vault, One Big Table, or something else? The real issue in data product modeling is not picking one universal schema. It is deciding which output ports, semantics, and interoperability guarantees the product needs.
There is no single right model for a data product. In practice, data product modeling is a data product design and data product architecture decision: you are defining the right output ports, semantics, and ownership model for a specific consumption pattern.
One practical way to make this manageable is to separate what must be standardized at the interface from what can remain flexible inside the data product. This is also where platforms like Witboost can help: making data contracts, metadata, lifecycle rules, and output port conventions explicit and governable.
Practical rules of thumb for data product modeling
The TL;DR version: If you only remember one thing from this expansive article, remember this one.
- Do not standardize one modeling technique across the enterprise.
Standardize interoperability requirements, contracts, identifiers, and output port conventions instead.
- Do not create a new data product only to change format, aggregation level, or physical structure
If the meaning stays the same, it is usually the same data product with another output port.
- Do not redistribute data from another domain through your output ports unless you are applying a semantic transformation
Copying data is not the same as owning its meaning.
- Keep joins, filters, and projections with the consumer whenever possible
Push them to the producer only when security, compliance, or platform constraints require it
- Denormalization is fine inside the same data product
If you are making the same domain data easier to consume, add another output port instead of creating a new data product.
- Create a new data product only when you are producing a new business concept
If combining inputs creates new domain meaning, new logic, or a new reusable concept, then a new product makes sense.
- Standardize the door, not the internal storage
Consumers need predictable ports, stable contracts, shared identifiers, and explicit semantics. They do not need every team to model internally in the same way.
- Shared entities need shared meaning, not shared tables
Interoperability depends more on identity, canonical semantics, and metadata than on forcing one physical model.
There is no single right data product model — only the right questions
A common enterprise mistake is trying to settle the data product modeling debate once and for all: one standard technique, one approved pattern, one enterprise-wide answer. That does not survive contact with reality.
Enterprises are not greenfield environments. They already have warehouses, operational systems, event streams, APIs, files, and teams with very different skills. Some data is relational. Some is document-based. Some is event-based. Some teams are comfortable with dimensional modeling. Others are not.
If you impose one technique everywhere, one of two things happens:
- You force source teams to remodel data in ways that do not match their systems or skills
- You flatten different consumption needs into one shape that serves nobody particularly well
That is why the first questions should be:
- What access pattern are we serving?
- Who is the consumer?
- What business meaning must remain stable?
- What interoperability guarantees do we need?
- What is the cheapest way to make the product usable and connectable?
A useful rule is simple: if a rule does not visibly help the consumer and does increase cost for the producer, it is probably not worth enforcing.
This is also why data governance should focus on guardrails, not on prescribing one physical design.
In Witboost terms, that means using templates, policies, and lifecycle checks to enforce what matters across teams — for example metadata completeness, data contract quality, protection rules, or promotion requirements — while leaving the internal model to the domain team.
Data product model types and when to use them
Different data product models fit different access patterns. In practice, the most useful distinction is between source-aligned data products and consumer-aligned data products, both of which should remain domain-driven and ownership-aware.
At the data product category level
A practical distinction is:
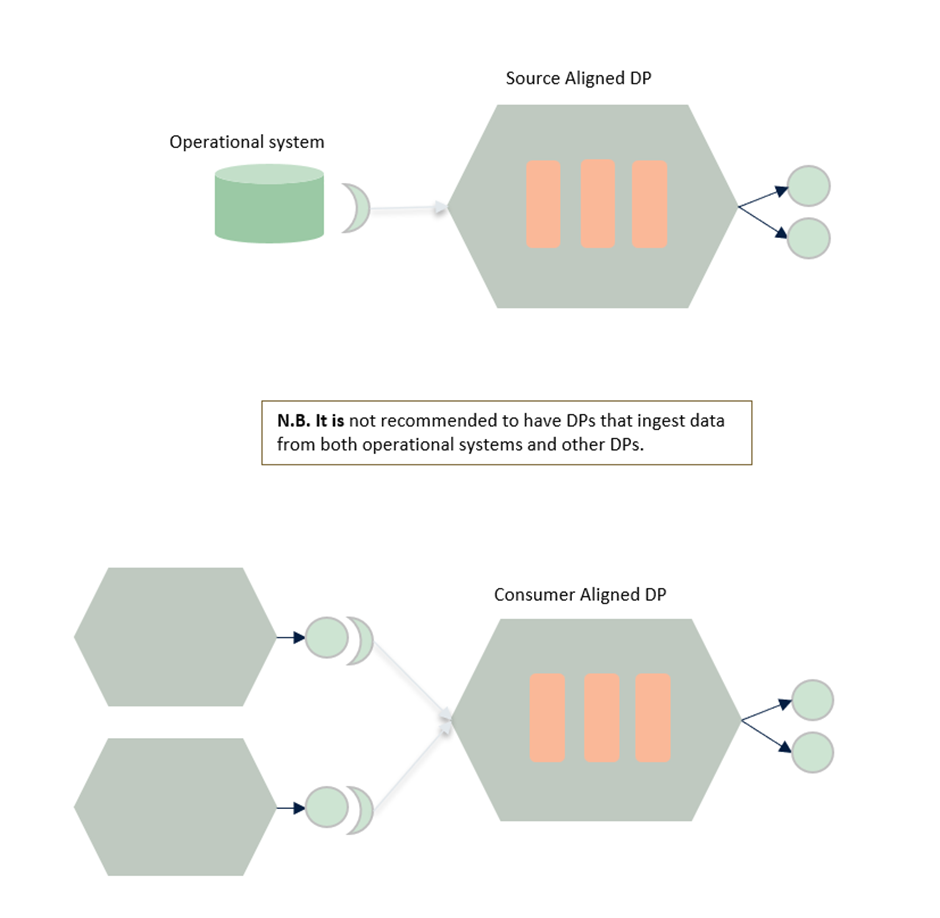
- Source-aligned data products: ingest data from operational systems
- Consumer-aligned data products: read data from other data products to serve a business use case
This is useful because so-called “aggregate domains” often become a vague category for technical reshaping without clear business value. If a product is only joining or reshaping data from other domains without creating a new business concept, it is usually not a new data product. It is often just an intermediate technical step.
In the following scenario, “the customer and payments” data product is just the result of merging information from two different data domains, without any specific domain logic or semantic transformation. In our view, this is not even a data product because:
- It is not adding business value
- It is just a technical step to improve performance and re-use
Aggregate domain data is not adding business value.
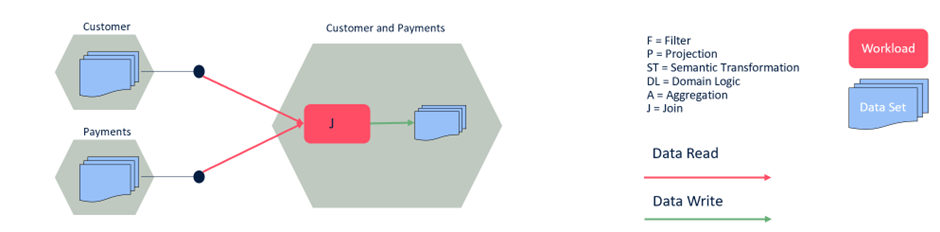
We suggest relying only on source-aligned and consumer-aligned data products, with the following simple rule:
- Source-aligned data product: is ingesting data from an operational system
- Consumer-aligned data product: is only reading data from other data products.
Source-aligned and consumer-aligned data products often need different governance paths across the data product lifecycl.
How to handle data from other domains
When you start data product modeling, it could be helpful to proceed in this way:
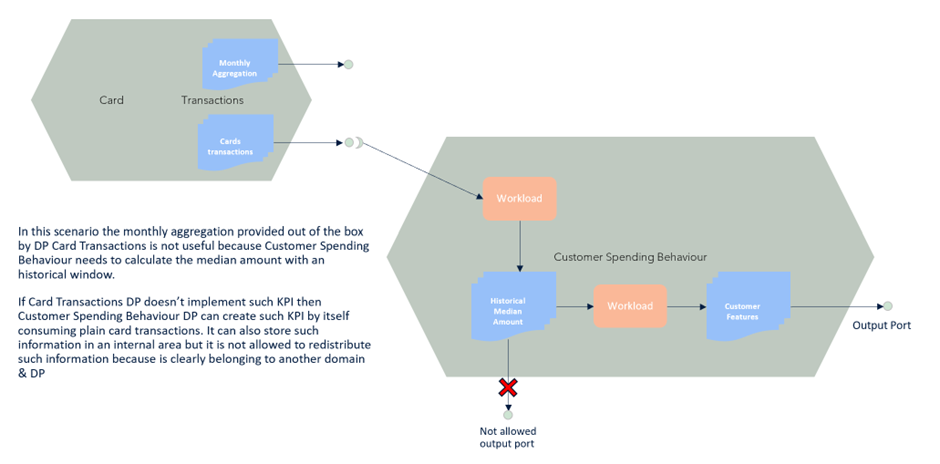
- If it is possible not to copy the data from other domains, and use and process them on the fly, go with that.
- Otherwise, if for some reason you need to accumulate them, do it in the internal storage of the data product, do not share them through output ports, and pay attention to managing them properly, taking into account compliance and data governance concerns.
- If you are transforming such information and you need to redistribute it with a different semantic meaning, pair it with the proper context maps information.
- As a last option, you can duplicate information if it is strictly helpful to make your dataset more meaningful and comprehensible to your consumers. The duplication should not be more than 5%-10% (rule of thumb) of the total number of information elements. The overall goal of the dataset is different from the source one.
The Witboost Way
This is one of the places where metadata and policy automation matter more than modeling theory. If a team republishes data from another domain, the important question is not only "what shape is the table" but "who owns the meaning, what is being transformed, and what is allowed to be exposed?"
Witboost can help make those decisions explicit through policy checks, access controls, and versioned descriptors that document what the product exposes and why.
How Output Ports shape data product modeling
If you want to know how to design output ports, start from the access pattern and the contract. Output ports are where data product interoperability becomes concrete, because this is where consumers see the schema, protocol, semantics, and guarantees.
Once you separate the internal model from the consumption interface, model choice becomes more practical.
| Port type |
Best for |
Typical modeling shape |
| Analytical SQL port |
BI, slicing, aggregation, exploration |
Star schema, dimensional model, sometimes One Big Table |
| Foundational analytical/file port |
Downstream data products, ML, integration |
Fine-grained, least-lossy relational or columnar structure |
| OLTP/API port |
Operational lookup, application access, agent consumption |
Entity-centric, key-addressable, normalized or document-oriented |
| Event port |
Propagation, reaction, streaming integration |
Event schema, append-only stream |
| File port |
Bulk movement, ML training, large-scale exchange |
Self-describing columnar files at declared grain |
This is exactly why output ports should be treated as explicit products of design, not as accidental by-products of storage. With Witboost, users can declare their output ports and their protocols as part of the data product specification. This helps teams standardize the “door” seen by consumers while still allowing different internal implementations behind it.
Physical structure vs. semantic interoperability in data products
This is the distinction that removes most of the confusion.
Physical structure
The internal structure of a data product is how the team stores, organizes, and processes data internally. That should remain largely a team decision, shaped by:
- Source system structure
- Domain logic
- Platform capabilities
- Team skills
- Performance requirements
Semantic interoperability
Semantic interoperability is what allows consumers to understand and combine data products correctly. This is what should be standardized. That includes:
- Shared identifiers
- Explicit grain
- Declared schema
- Stable data contracts
- Canonical definitions for shared concepts
- Predictable output port conventions
- Versioning and change management
- Security and masking rules at the port
A well-formed output port should make freshness and data quality guarantees explicit, which is also central to data product observability:
- One access pattern per port
- Declared shape and grain
- Shared identity and semantics
- Freshness and quality guarantees
- Protection rules
- Stability and versioning
When producers start modeling for consumers, ownership breaks down
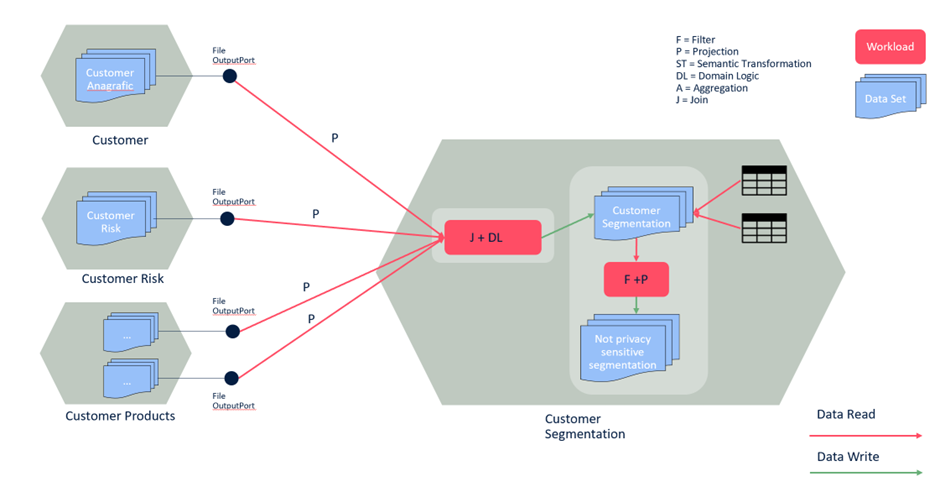
When a producer is exporting data according to consumer requests (maybe coming from a different domain), there is a high risk that the producer will end up implementing some domain-specific logic or semantic transformation belonging to the consumer. This would be a clear violation of the domain-oriented ownership principle.
If we implement interoperability accurately, the consumer will probably be in the position to apply filters and projections on the fly by itself. The data producer should be in charge of generating new output ports with embedded filters and projections only if it is required for security and compliance reasons because they are accountable.
This is an important governance boundary. A data producer should expose a stable, well-described interface. A data consumer should compose that interface for its own use case. If every consumer-specific projection gets pushed back into the producer, the producer stops owning a domain data product and starts acting like a central reporting team again.
Witboost can help here in a subtle but useful way: formalizing subscriptions and access requests around the data product interface. This makes it easier to distinguish a legitimate producer-owned port from a consumer-specific customization that should stay downstream.
Shared entities, polysemes, and canonical meaning
Sooner or later, data products need to connect across domains. That is where physical modeling differences become less important than semantic consistency. Take a shared entity like customer.
One domain may expose customer in a wide analytical table. Another may expose it as a normalized entity. Another may emit customer-related events. These are different physical representations of the same real-world concept.
In Data Mesh language, these are often treated as polysemes: the same entity represented differently across bounded contexts. That is not a problem by itself.
The problem starts when the enterprise assumes that shared entity names automatically imply shared meaning. They do not. To make shared entities interoperable, you need a small canonical layer for the concepts that actually cross domains.
That usually means:
- A business glossary or ontology
- Canonical definitions for shared entities
- Explicit mapping from local representations to shared meaning
- Shared identifiers that allow products to connect confidently
This canonical layer should stay at the metadata and interface level. It should not force every domain into one monolithic physical schema.
Why identity and Master Data Management matter
Shared meaning breaks down quickly if identity is weak. A shared identifier is not just a technical field. It is an enterprise commitment that different data products referring to the same entity can actually be connected. That only works if someone is responsible for:
- Assigning or governing the identifier
- Keeping it unique
- Resolving duplicates and conflicts
- Deciding which domain owns the entity definition
- Maintaining trust in cross-domain joins
This is where identity resolution and Master Data Management matter. Master Data Management should not be treated as a giant monolithic schema that every team must conform to physically. That approach usually recreates central bottlenecks.
A better view is this:
- Master Data Management is a discipline for identity and canonical entity governance
- It is not necessarily a single physical data product
- It should resolve identity as far upstream as possible
- It should support shared entities without forcing one storage model everywhere
Without identity resolution, cross-product joins are often just coincidences of column names. With identity resolution, they become meaningful and durable.
How to model data products: the key questions to ask
Instead of starting from technique, start from a decision framework.
1. What consumer and access pattern are you serving?
Are you serving:
-
another data product
-
BI and analytics
-
machine learning
-
operational applications
-
event-driven consumers
-
AI agents
2. Are you exposing the same meaning or creating a new business concept?
If you are only changing structure, format, or aggregation level, stay within the same data product. If you are creating new domain meaning through semantic transformation or business logic, a new data product may be justified.
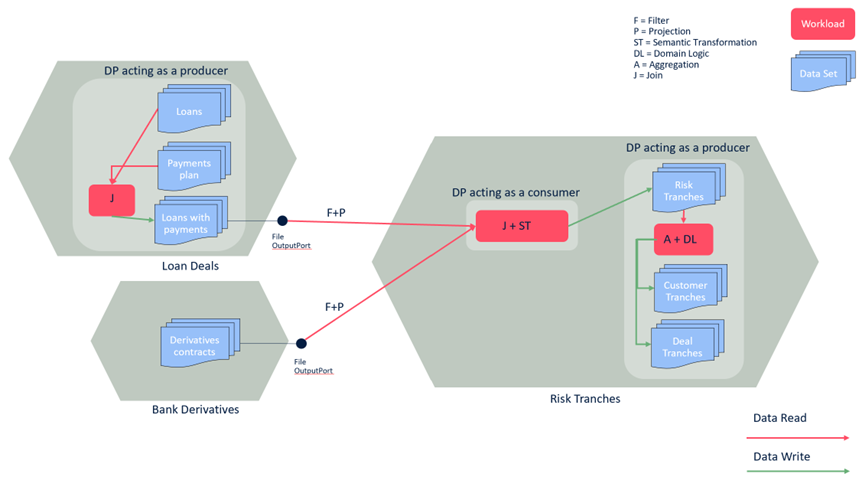
Suppose you are generating a new business concept that belongs to a specific domain (Risk). If you need to join multiple data domains and apply some semantic transformation (that is always hiding domain logic), then it is worth creating a new data product because you are creating a brand-new business concept.
For example, in Risk Tranches we convert installments coming from in risk components, that is a semantic transformation.
Otherwise, if you are aggregating data that already belongs to your data product, even if you apply specific domain logic, it means you are in the same bounded context. It means you have to add a new Output Port to the same data product, because probably you only need to apply some denormalization to make the data more consumer-friendly.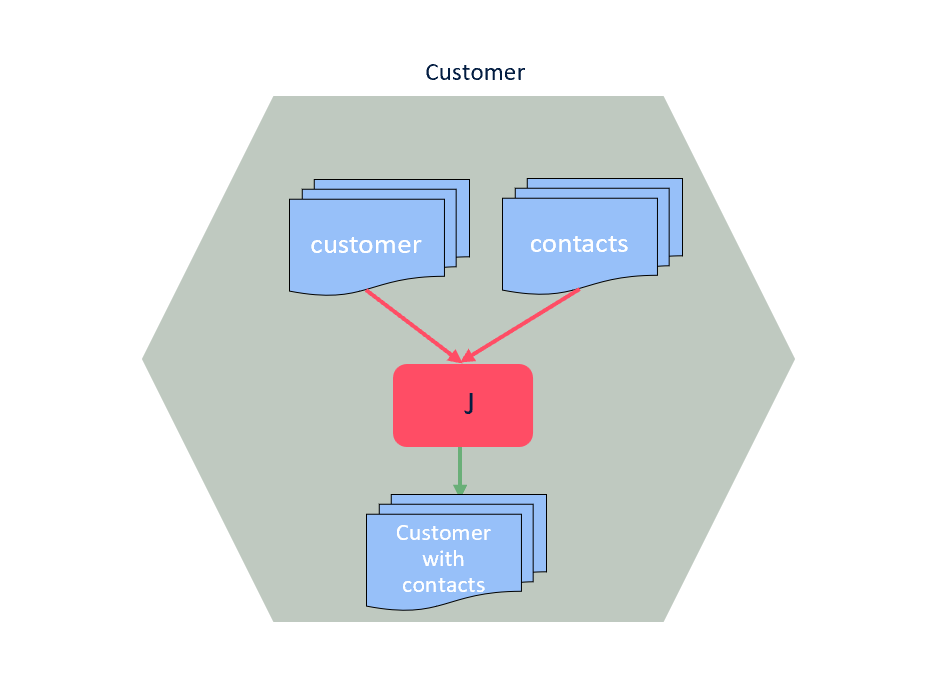
3. Does the data belong to your domain?
If the core data belongs to another domain, do not redistribute it through your output ports unless you are applying a semantic transformation and making ownership explicit.
4. Can the consumer apply joins, filters, and projections?
If yes, let the consumer do it. If no, or if security/compliance requires producer-side enforcement, expose a dedicated port or projection.
5. What level of loss is acceptable?
Human-facing consumption often benefits from denormalization and shaping.
Downstream data products usually need the least-lossy, finest-grain version you can expose.
6. What must be standardized for interoperability?
Usually you need to standardize:
Usually you don't need to standardize:
7. Do you need history, and what kind?
Do consumers need current-state lookup, historical reconstruction, or both?
8. Will this rule help consumers enough to justify producer cost?
If the answer is no, do not enforce it.
| Question |
If yes |
If no |
| Are you creating new business meaning? |
Consider a new consumer-aligned data product |
Stay in the same product |
| Are you only changing shape for a consumer? |
Add an output port |
Do not create a new data product |
| Does the data belong to another domain? |
Avoid redistribution unless semantics change |
Proceed within your domain |
| Does the consumer need a specific access pattern? |
Design the port for that pattern |
Keep the interface minimal |
| Do shared entities cross domains? |
Enforce identifiers and canonical semantics |
Keep semantics local |
Final thoughts
Good data product modeling does not come from standardizing one schema. It comes from standardizing meaning, contracts, identifiers, and output ports in a way that scales across domains. The better way is much simpler:
- Keep internal modeling flexible
- Standardize output ports and data contracts
- Protect semantic ownership
- Make shared entities explicit
- Treat identity as foundational
- Create new data products only when new business meaning appears
That is how you get interoperability without just giving your data monoliths a different shape.